
By Starktronix EngineeringNotes from our own systems
Listen to this article · 3 min
A user reported that adding cards to a board sometimes failed with a 500. We could not reproduce it. We added cards, they worked. We added a lot of cards, they worked. We asked what they were doing differently and the answer was: nothing, I was just going fast.
Read, increment, write
Every card gets a human-readable key — `BIGG-1`, `BIGG-2`. The allocator did the obvious thing: select the highest existing number for the project, add one, insert the row. Three statements, no transaction, no unique constraint doing any work in between.
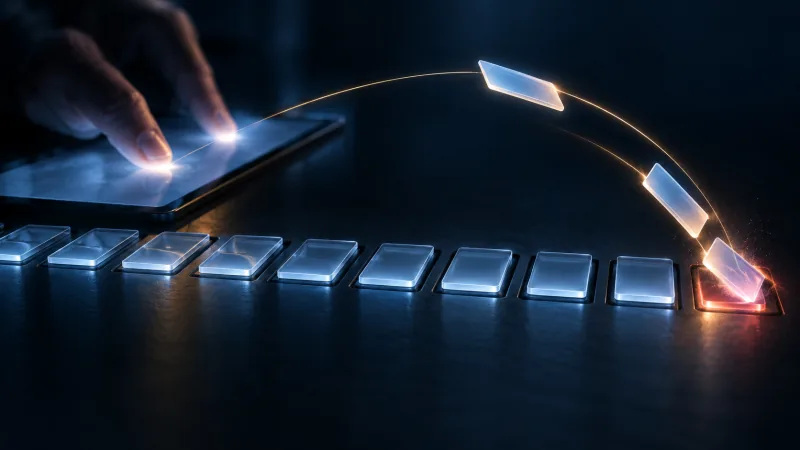
Two requests arriving close enough together both read the same maximum. Both computed the same next key. The first insert succeeded; the second violated the unique constraint and surfaced as a 500. The window is a few milliseconds wide, which is exactly the width of a person clicking quickly.
Read the maximum key
Two requests arriving close together both select the same highest existing number.
Compute the next key
Both requests add one to the same maximum, producing identical keys.
First insert succeeds
The first write lands cleanly.
Second insert fails
The second violates the unique constraint and surfaces as a 500.
It was not a rare bug. It was a common bug with a narrow trigger, and the trigger was competence.
Reproducing it
The reproduction was the whole job. Once we stopped trying to reproduce by *volume* and started reproducing by *concurrency* — eight writes fired in parallel rather than eight hundred fired in sequence — it failed on the first attempt, every attempt. Sequential load will never surface a race, no matter how much of it you generate.
The fix
We kept the constraint and retried against it. On a unique violation, re-read the maximum and try again, with a bounded number of attempts. The alternative — a database sequence per project — is cleaner in isolation but changes the key semantics, and the keys are user-visible and already in circulation.
Chosen fix
Retry on conflict
Keep the unique constraint; on a violation, re-read the maximum and try again, with a bounded number of attempts.
Rejected alternative
Database sequence per project
Cleaner in isolation, but changes key semantics that are already user-visible and in circulation.
This is worth being explicit about: the constraint was not the problem. The constraint was the only thing that stopped two cards from silently sharing a key, which would have been a data-integrity bug rather than an error message. The 500 was the system telling the truth in an unhelpful tone of voice.
What we changed beyond the fix
Every read-modify-write in the codebase got looked at. Two more had the same shape. Neither had been reported, because neither had a user fast enough yet.
And the test harness grew a concurrency mode. Eight parallel writes now land clean, and that assertion runs on every change to the allocator. If someone reintroduces the race, the suite finds it before a fast user does.